
Maths
The Transformers from first principles module assumes linear algebra, calculus and probability. You study them at home, from modules on our learning platform, and we run one refresher workshop in week 25, the week before it starts.
We teach one programme, a Level 6 machine learning engineer apprenticeship for experienced software engineers. Workshops run in person near Old Street, one afternoon a week, from 2pm to 6pm. The next cohort starts on 27 October 2026.
We bring together experienced engineers from different industries and work through the modern deep learning and agentic engineering stack. You come in one afternoon a week, for 58 workshops. With breaks, that takes about 15 months. The programme runs in three terms, with breaks at Christmas, in the spring and at the end of the summer, and the week numbers count teaching weeks only. If you want to move faster, you can finish after 12 months.
The work is meant to be used. Four of the seven modules are projects, and if your employer has a problem that fits, you work on that. In the last module you build an AI system for your employer and put it into service.
The first thing you write is a coding agent, from scratch. We give you a server, and you turn it into a Kubernetes cluster and serve the models you train from it for the rest of the programme. You build retrieval with hybrid search, reranking, and an agent that searches for itself. Later you build a transformer from the ground up in PyTorch. In Frontier ML each afternoon goes to one paper, read in the room and reproduced at small scale.
We provide a server, GPU access, and OpenAI, Claude and OpenRouter credits for the workshops. Practitioners lead them, and speakers come in from organisations such as Google DeepMind.
Things are moving very fast, and we are doing our best to keep up. Where we see opportunities, we’ll improve things, so you should treat this curriculum as indicative rather than definitive.
 Python
 NumPy
 scikit-learn
 XGBoost
 PyTorch
 Hugging Face
 Claude Code
 MCP
 MLflow
 FastAPI
 Postgres
 Docker
 Kubernetes
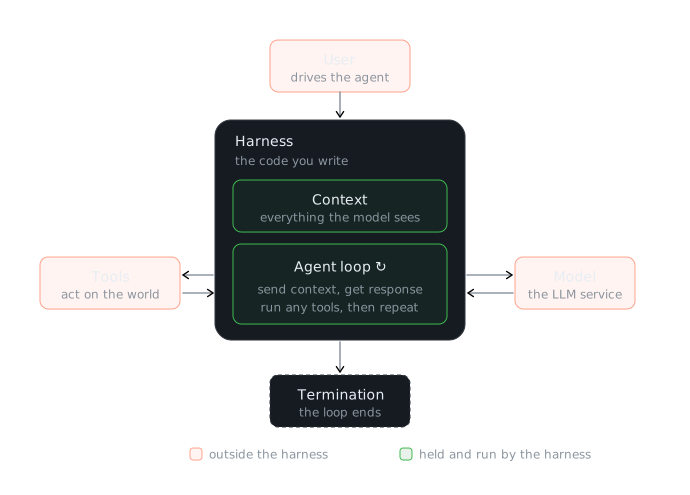
An agent is a language model using tools in a loop. The harness is everything in that loop except the model, from the context it is given to the checks that run on what it produces.
In the first workshop you write a coding agent from scratch, a small working version of Claude Code. In the second you look at harness engineering, and at the controls that improve what Claude Code produces. One short session goes to the Model Context Protocol. The rest of the module is a group project, and it ends with presentations.
PythonClaude CodeMCPDocker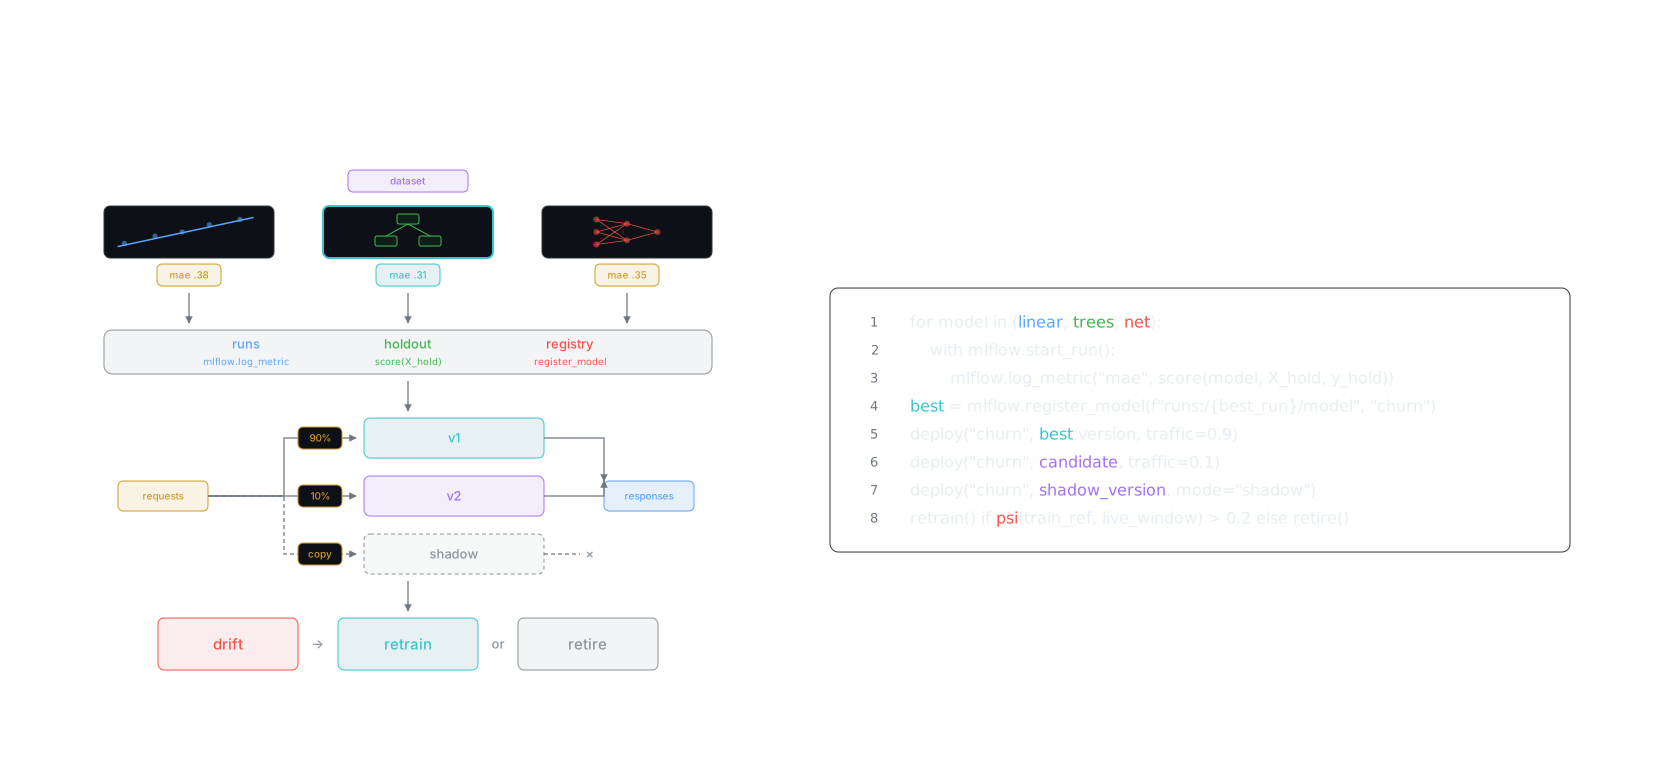
You start with raw data and end with a model answering live requests. The aim is to do a machine learning engineer’s job once, end to end.
You curate the data, then fit a linear regression baseline, gradient-boosted trees and a small neural network, score all three on the same held-out split, and log every run to MLflow.
You serve the model behind FastAPI on your own Kubernetes cluster, then change it while it is running, with a second version on 10% of the traffic and a third as a shadow on a copy of every request. In the last workshop you look at data drift, and at whether to retrain the model or retire it.
Pythonscikit-learnXGBoostPyTorchMLflowFastAPIDockerKubernetes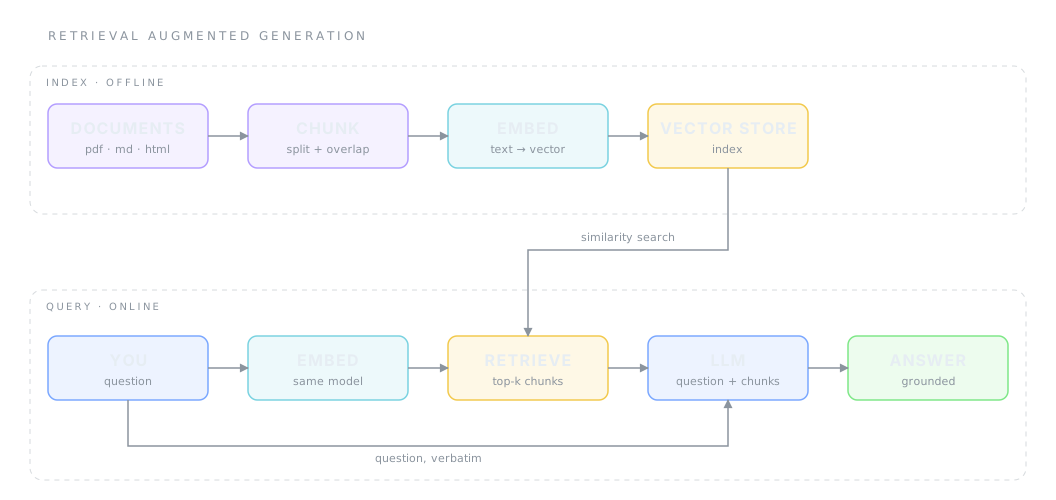
Context engineering is the job of getting the right data in front of the model. Retrieval is how you do that when the corpus is too large to load.
You start with RAG as it was built in 2023. Documents are chunked, embedded and stored in pgvector. A query is embedded, the nearest chunks come back, and they go into the prompt. You build it first on a hosted embedding API, then on a local model, then strip it down to cosine search in NumPy. You write the test questions before any of that, part by hand and part generated, check the generated ones against human judgement, and score every change on precision, recall and mean reciprocal rank.
Then you move on to what the field does now. A BM25 index sits beside the dense one and the two are fused by reciprocal rank fusion. A cross-encoder reranks the shortlist before it reaches the model, and you measure what that costs in latency. After that the model takes over retrieval. An agent with search tools decides what to fetch, judges what came back and fetches again, and you score it against loading the whole corpus into the window. The last taught afternoon is LLM operations. You route requests between a cheap model and a reasoning model, cache what repeats, version the prompts, track what every call costs and add a fallback for when a provider fails.
The module ends with a group project, a retrieval system over a set of documents, ideally your employer’s.
PythonNumPyHugging FacePostgres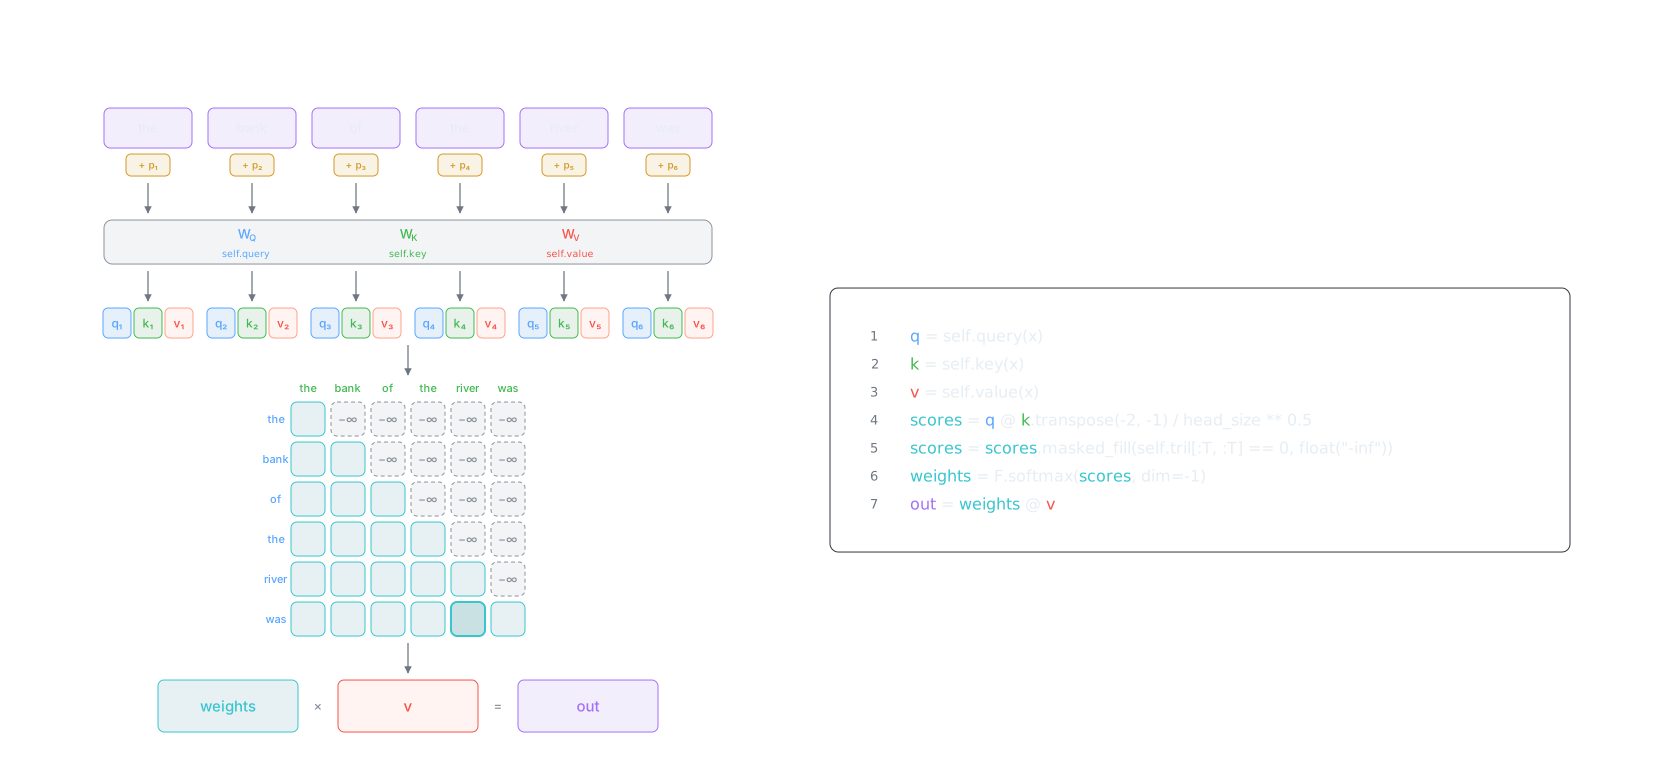
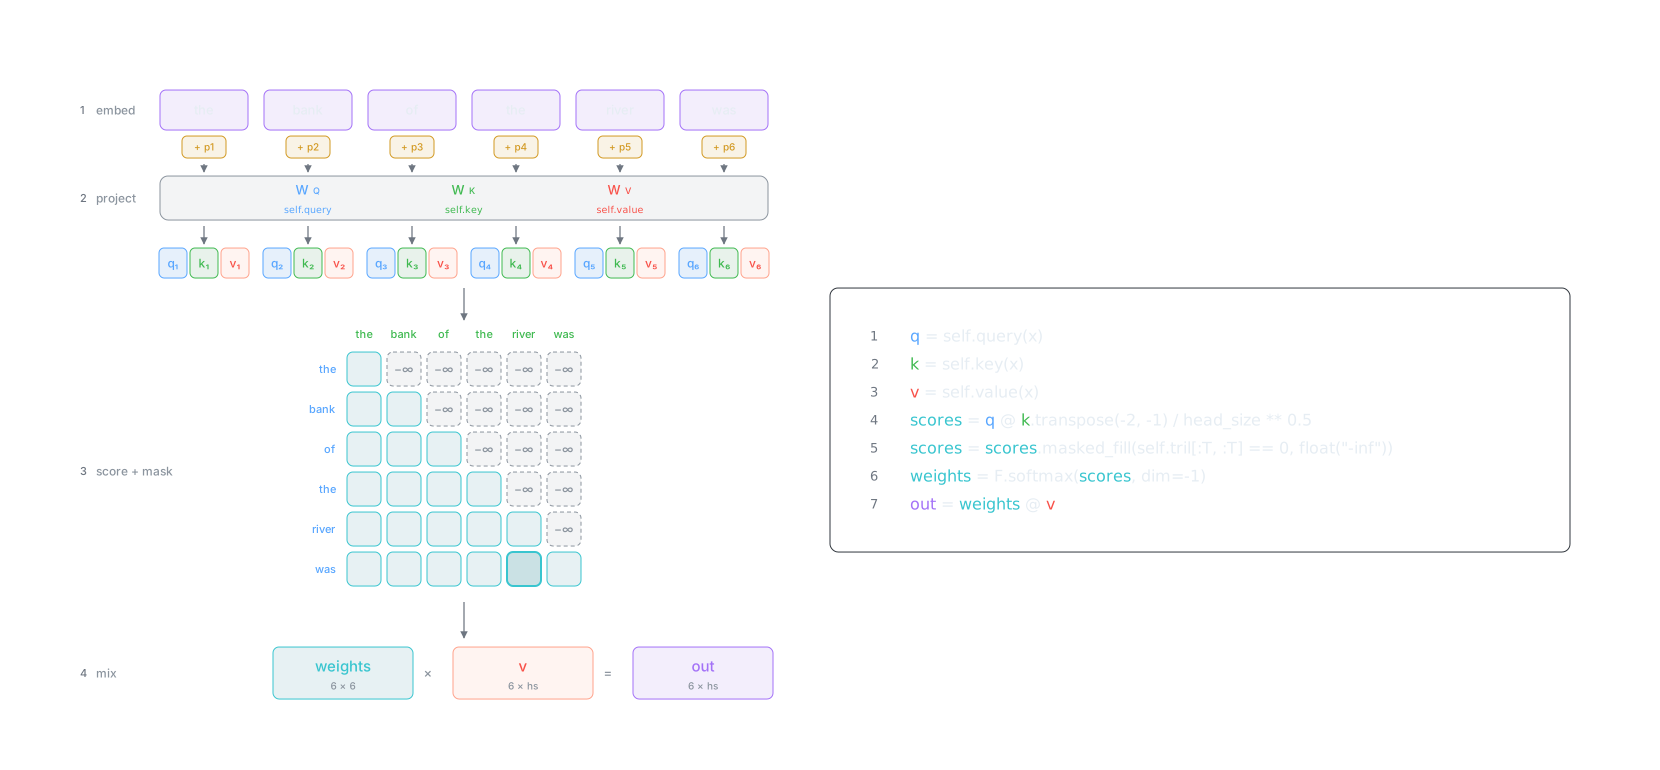
You build a transformer from the ground up in PyTorch. The aim is to understand the substrate at the heart of the current AI boom.
You read the foundational papers alongside the code, starting with ‘Attention Is All You Need’, and the engineering decisions in your model come from them. Attention comes first, worked out by hand on one sentence before it goes into code, then the rest of the block, then training on a small dataset. Towards the end of the module you train a model on a GPU with mixed precision and fine-tune a small open model with LoRA.
By the end of the module you have a clear idea of what deep learning researchers do day to day.
PythonNumPyPyTorchHugging Face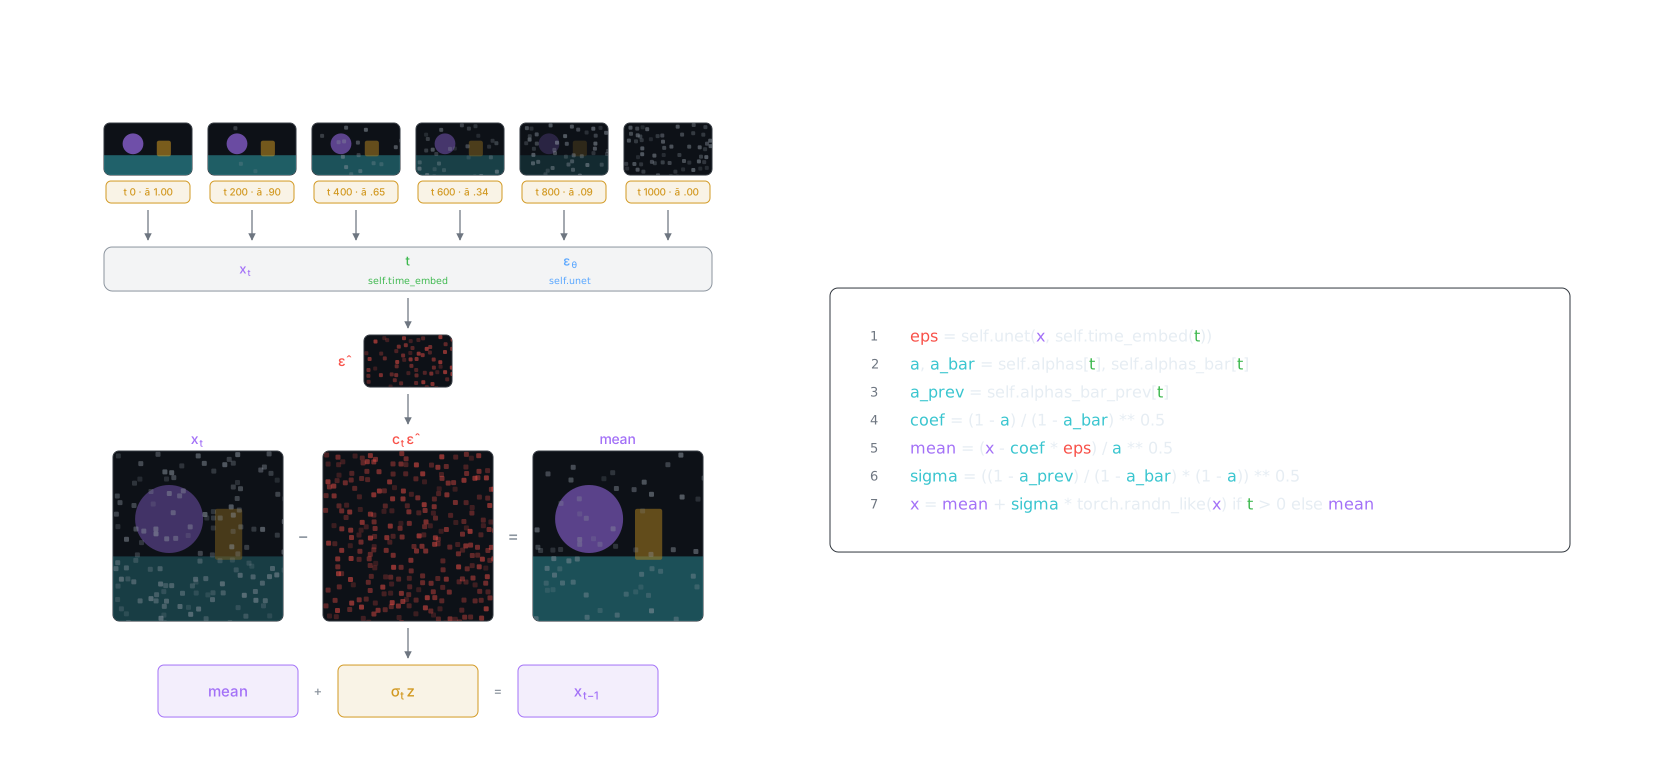
This module has no fixed syllabus. We choose the papers eight weeks before it starts, from whatever the field is arguing about at the time.
Each afternoon goes to one paper. You read it in the room, argue over it at the whiteboard in groups of four, then reproduce part of it at small scale and take the implementation as far as the afternoon allows.
PythonPyTorchHugging Face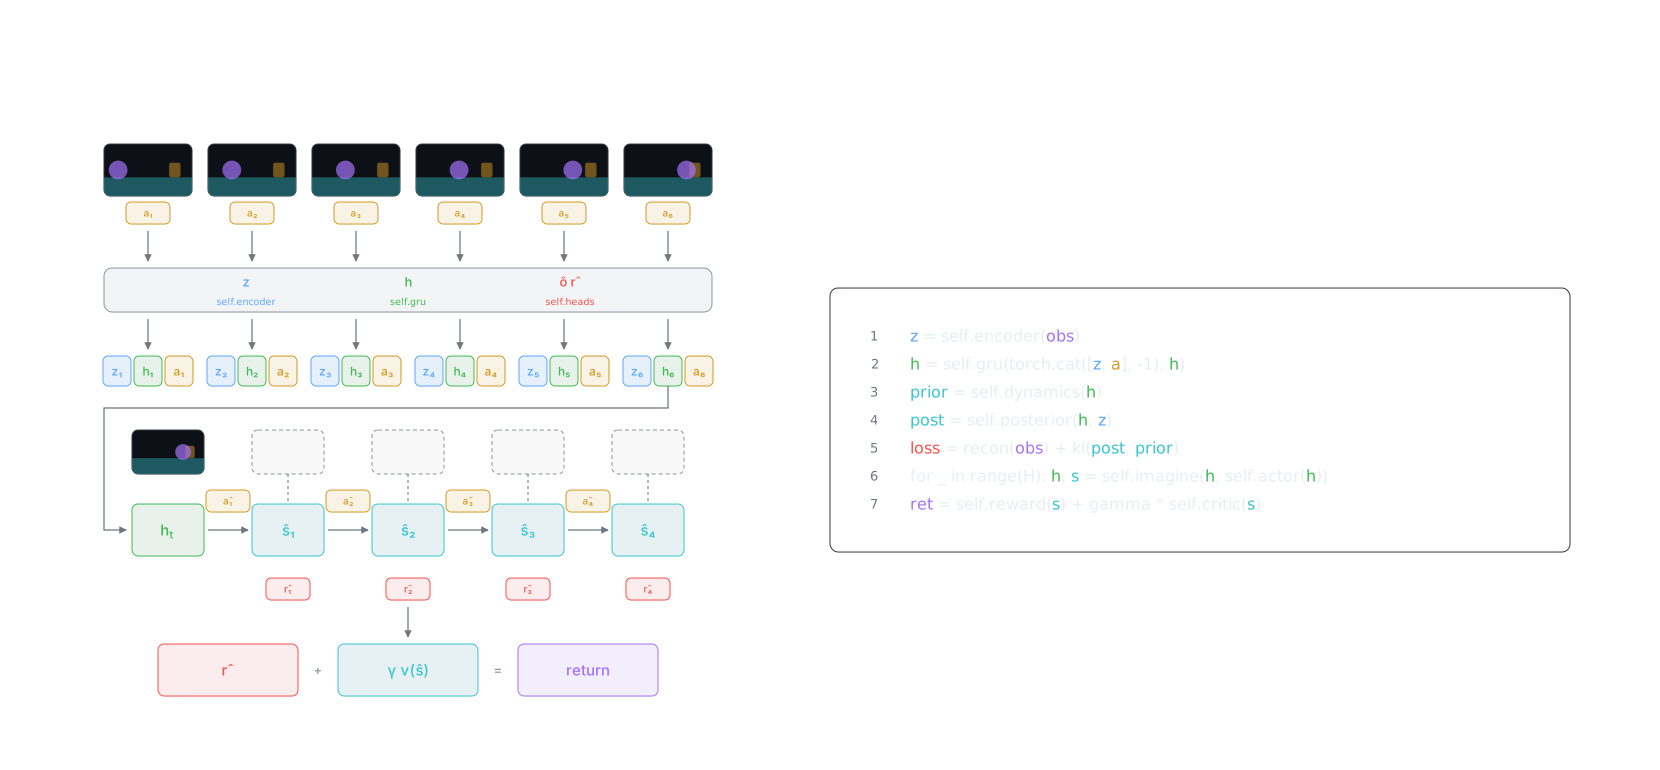
Your team picks a paper and a problem, ideally one set by an employer. You reproduce the paper’s result at small scale, then apply it to the problem.
The one rule is to serve early. By the second week the team has a model in service, on a cluster one of you already runs, and at the end you know what it cost.
PyTorchHugging FaceDockerKubernetes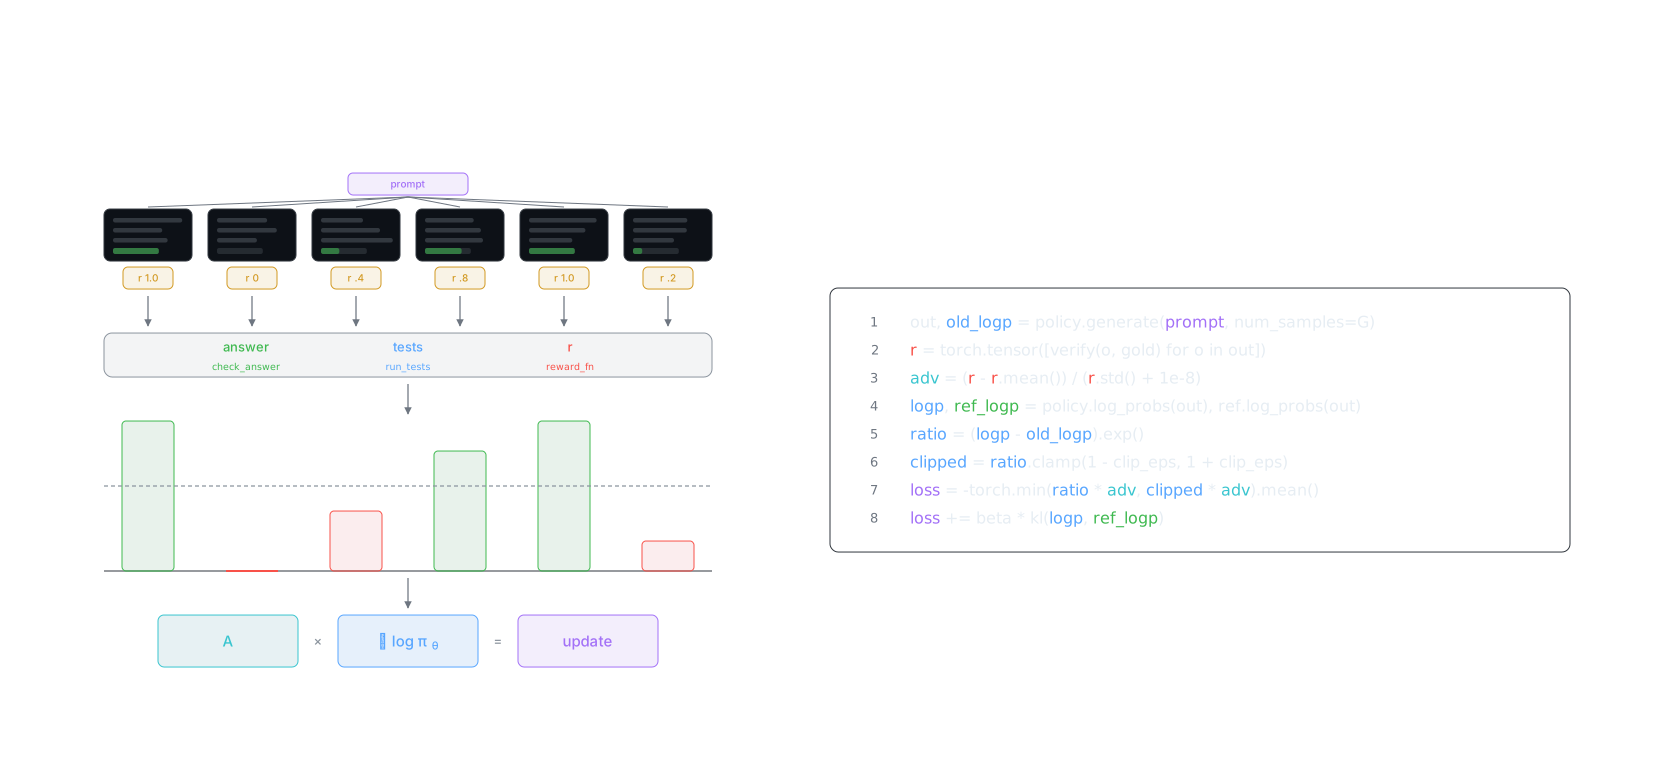
You build an AI system for your employer, to a brief they set, and put it into service. Your assessment and grade are based on that work.
The cohort reviews your work twice, first on the architecture and the data, then on the evaluation and the risks. You document the system, hand it over, and present it first to the cohort and then to your employer.
PyTorchMLflowDockerKubernetes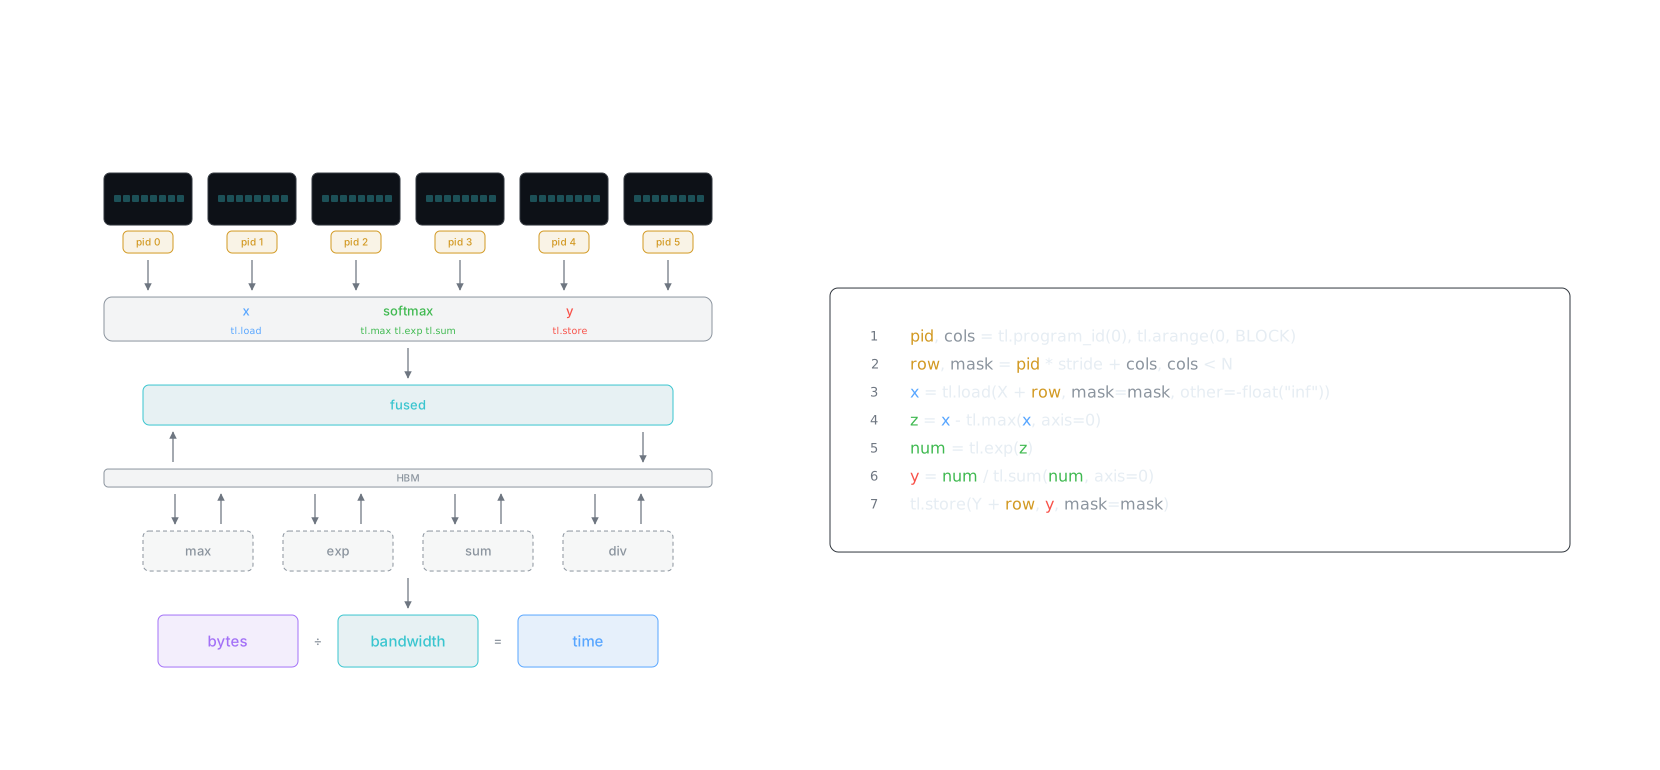
The first afternoon starts with lunch. You meet the cohort, hear what the next 15 months hold, and set up your tools.
You read 100 traces from the agent you built and sort its failures by type. You then write an automated judge and measure how often it agrees with you.
We give you a server and you turn it into a single-node Kubernetes cluster with DNS, ingress and TLS certificates. It is yours for the rest of the programme, and you serve the models you train later from it.
An agent is open to attack when it holds private data, reads untrusted text and can send messages out. You attack each other’s agents by prompt injection, jailbreaking and data extraction, then close the holes in your own with input validation and output filtering.
We revise the linear algebra, calculus and probability that the next module relies on.
You build a voice agent, either on a real-time speech API or as a pipeline of speech recognition, a language model and speech synthesis.
Most of a machine learning system is other people’s models, datasets and libraries. You look at what can be hidden in them, and you test a model for bias before you release it.
You write a fused softmax kernel in Triton and profile it against the PyTorch version, then read the FlashAttention kernel line by line. Memory bandwidth limits these kernels more than arithmetic does.
More capable systems bring new risks, including misuse and agents that act with too much autonomy. You read how labs evaluate a model for dangerous capabilities, and how they decide whether it is safe to release.
The Transformers from first principles module assumes linear algebra, calculus and probability. You study them at home, from modules on our learning platform, and we run one refresher workshop in week 25, the week before it starts.
We run a pre-course before the programme starts. Come to as many of those sessions as you can.
Each place costs £22,000, and the government pays all of it through the apprenticeship levy. Larger employers have already paid for the training through their taxes. For smaller employers, our partners pay the full cost. We can explain the levy when you speak to us.
The apprenticeship ends with an assessment in two parts. The first is a written report and a presentation on the system you built for your employer. The second is a discussion of your work with an independent assessor.
The first workshop is on 27 October 2026, from 2pm to 6pm.